Three panel side-by-side comparison of common AI generation flaws…
By @legion ·
7 likes · 12 comments
The Generics.
Tags
- ai generation error
- ai art fails
- generative ai mistakes
- ai rendering flaws
- portrait comparison
- ai generated portrait artifacts
- triptych portrait
- plain studio background
- misspelled ai text output
- machine learning errors
- ai consistency test
- generative output examples
- ai fail compilation
- parallel lives
- multiverse concept art
- ai generated art
About this image
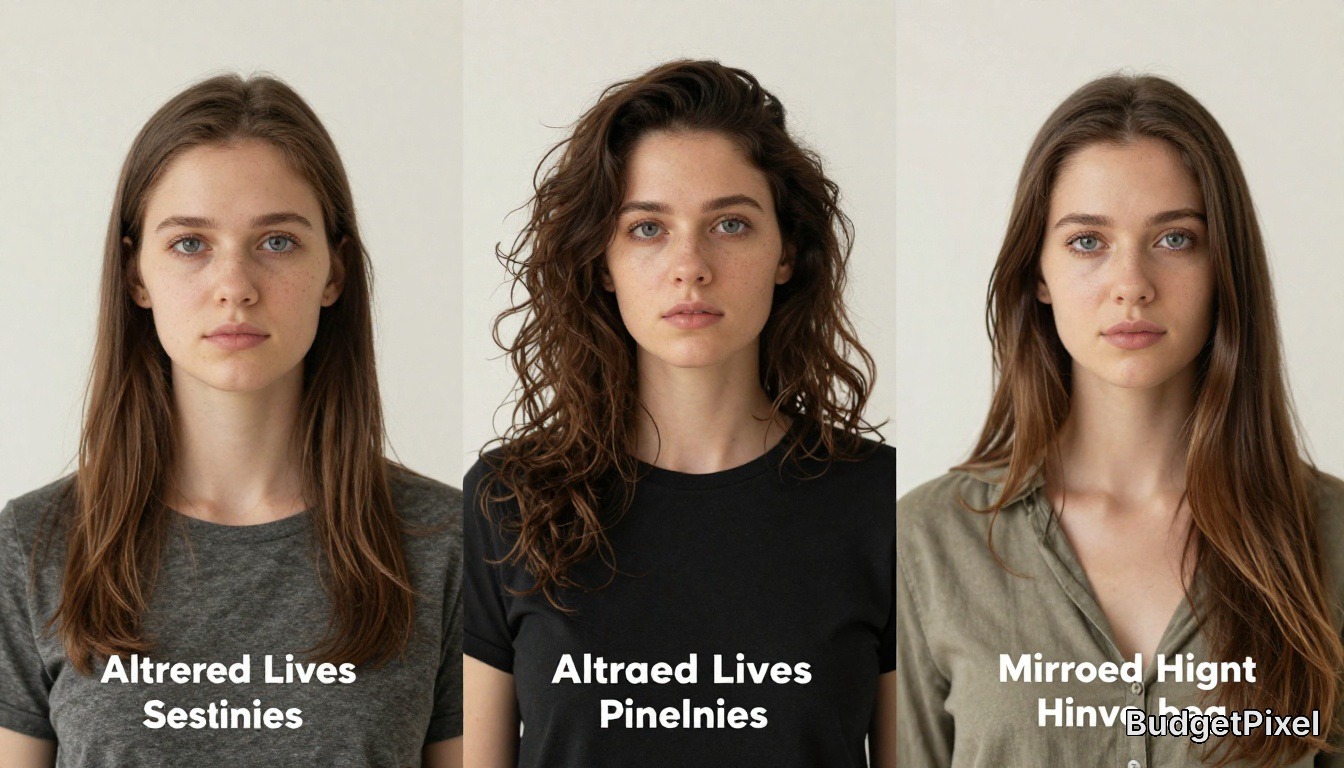
This side-by-side triptych demonstrates common AI image generation errors, featuring three slightly varied portraits of the same young blue-eyed, freckled woman against a plain neutral off-white background. Each panel includes nonsensical, misspelled generated text overlay, plus subtle differences in hair texture, shirt color, and small facial rendering quirks that indicate generative AI inconsistencies. The minimalist, soft-lit composition highlights typical flaws that appear when AI tools generate consistent human portraits and legible on-screen text.
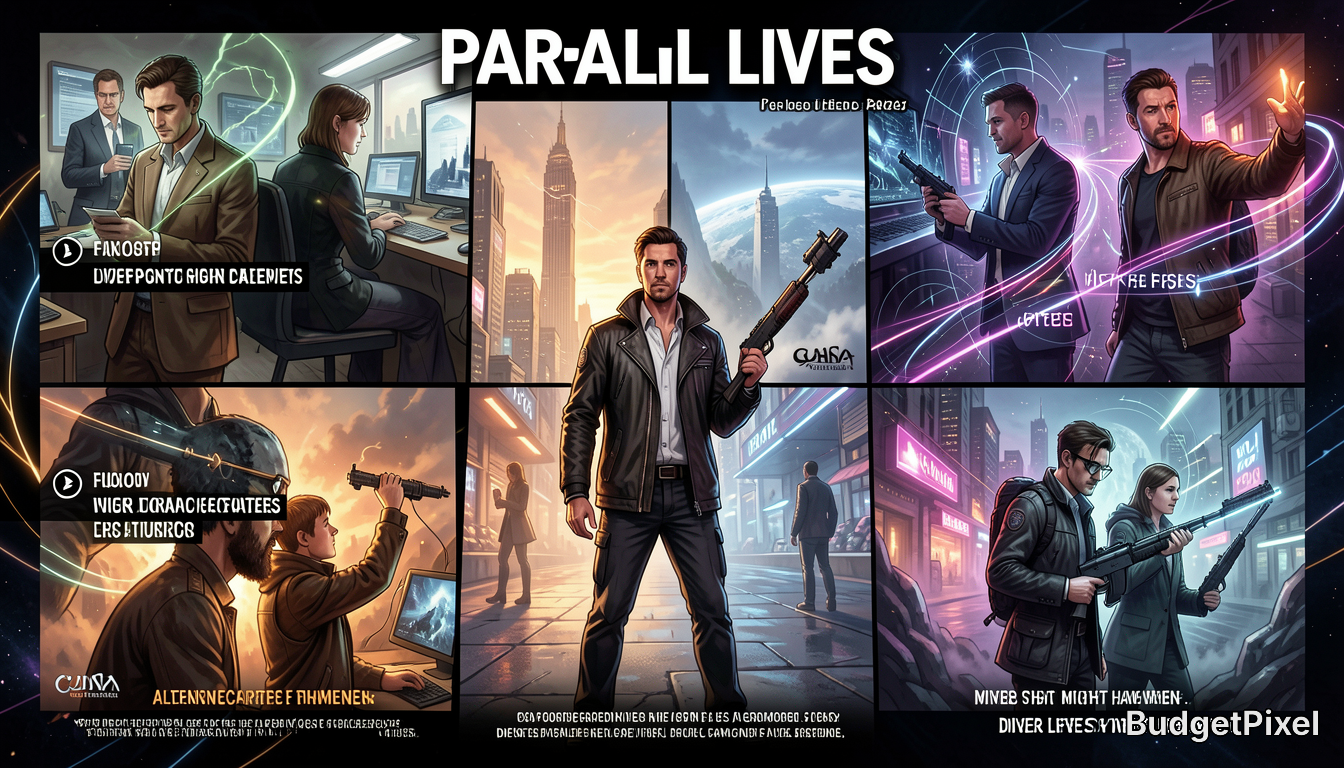
This AI-generated sci-fi concept art titled "PAR-ALIL LIVES" uses a comic panel grid layout to explore parallel universe timeline themes, showing alternate versions of the same man across wildly different realities from everyday office life to cyberpunk action hero. The stylized digital illustration features dramatic cinematic lighting, a mix of warm sunset and glowing neon purple color palettes, futuristic city backdrops, and characteristic garbled text consistent with generative AI artwork. The central panel anchors the collection with an action hero protagonist holding a rifle, surrounded by side panels depicting work, combat, and magic power alternate life scenarios.
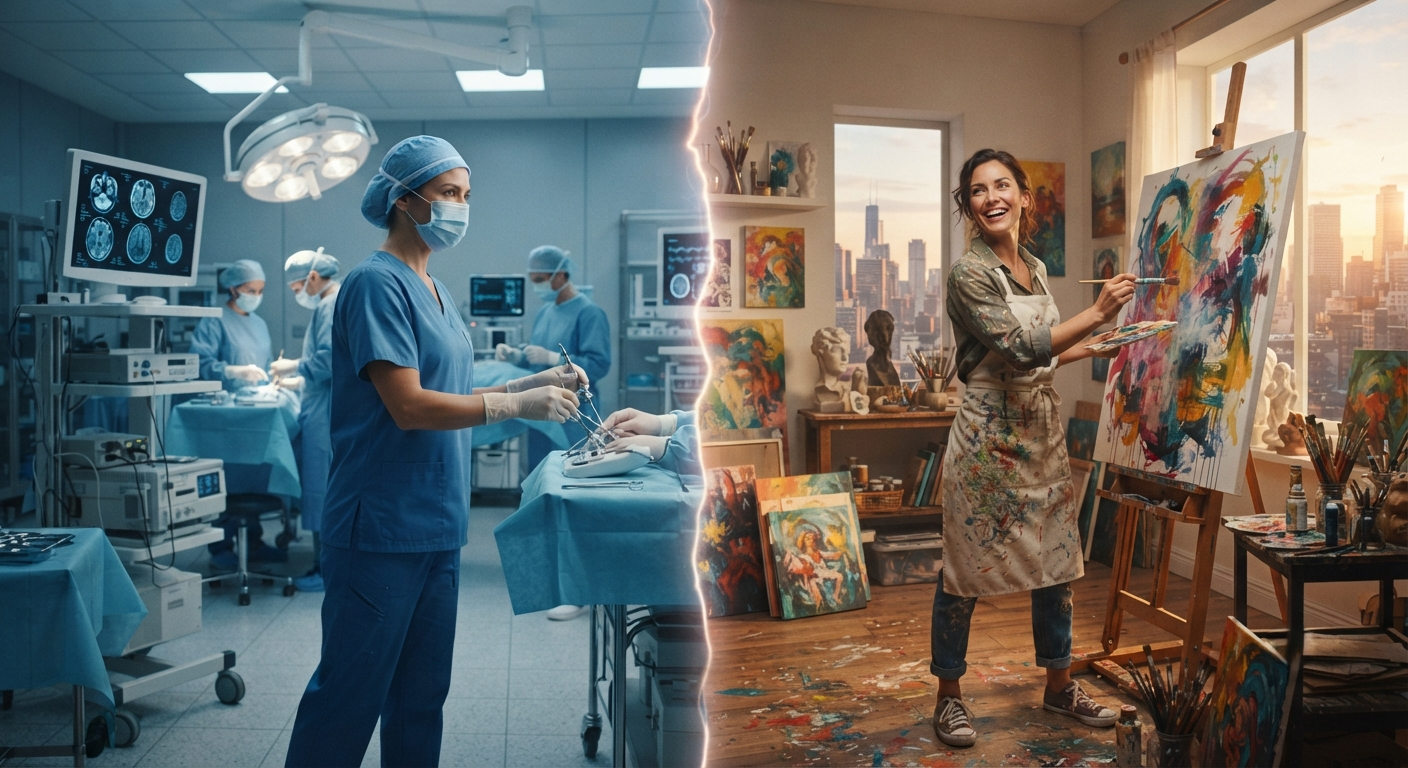
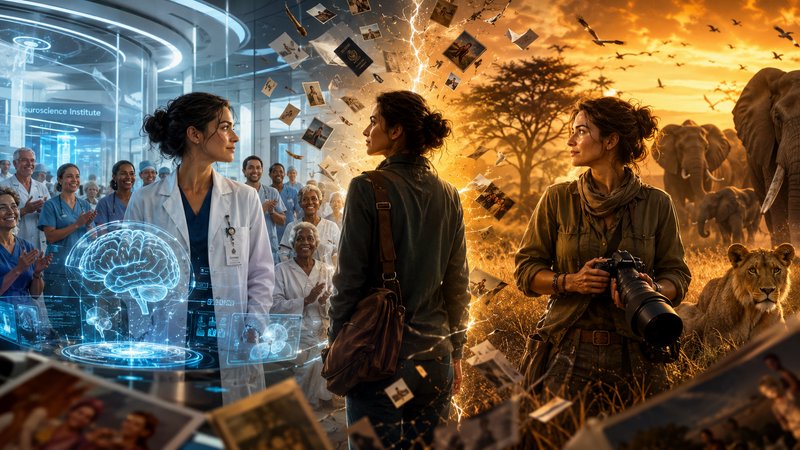
This conceptual split composite artwork illustrates the duality of a creative medical professional, juxtaposing two parallel lives side-by-side. The cool-toned left half depicts a female surgeon in blue scrubs working in a sterile operating room with medical imaging monitors and a surgical team, while the warm-toned right half shows the same joyful woman painting a vibrant abstract canvas in a sunlit city-view art studio. The contrasting cool and warm palettes highlight the balance between a rigorous medical career and expressive creative practice, with an uplifting, aspirational mood.
Comments (12)
@legion ·
Let me explain: the first two are standard and generic; I believe the first was created with P-Imagen and the second with Flux Klein. I tried generating a third one using the free version of Qwen, but it didn't work—it didn't even generate an image; it simply threw an error—so it strikes me as an unreliable engine. The third one, however, is from Gemini, and the fourth from GPT; since they are superior, the leap in quality is truly noticeable. That said, the prompt used was the same one that appears in the challenge header. I usually opt for budget-friendly options to generate the generic ones, so this time is different.
No wonder they are so different. I only do the cheap ones when I am doing an all model comparison because they tend to drop elements of the prompt. At 25 credits, Flux 2 Pro is not too bad and it generally doesn't drop much. I haven't used Flux Klein or Schnell models that much but they are cheap. I'd have to check my all model comparisons to see how much they drop. Minimax drops some and has a tendnecy towards reality but once in awhile it surprises me. ZiT is often slow on BP which is weird because it's fast on NC
@legion ·
I used to create generic images with P-Image, Z-Image, and Minimax, but now—to take advantage of the free daily allowances—I use Flux Klein and Qwen. However, once I have a clear idea in mind, I switch to ChatGPT (which allows for 3 or 4 daily generations) and Gemini (which allows for 20); then, I choose the best one from the bunch for the challenge.I like the way you analyze all the models; were you always so studious?
I don't know about studios. It just fascinates me how one prompt can look so different in each model but at the same time, how within each model there seems to be more consistency with same prompts.
I agree time makes a difference. The more computational time the AI has, usually the better the result. The other big difference is seed but generally we can't see those
@legion ·
It's probably because each one is programmed and trained differently; also, it depends on the time—the more training there is, the better the results, I'd say...
@legion ·
Exactly, it’s like its age: the more time passes, the more the AI learns and the better it works—unlike some people... hahaha.😄
wow! this time the generics were all over the place. Usually they are more similar. It's very interesting
La cuarta creo que todos tuvimos esa alternativa o similar jaja, era lo mas usual
@legion ·
si,totalmente generica,gacias por pasar!
Sign in to join the conversation.
More from @legion
See all → VideoVintage CRT television displaying grainy monochrome footage overlaid with bold red Canal Satan title text
 Glowing coral arch frames a fantasy undersea kingdom with a shell palace, jellyfish lanterns, and swimming manta rays
 Whimsical glowing underwater fairy tale castle surrounded by cartoon fish and vibrant coral on the ocean floor
 Glowing underwater seashell palace with merfolk riding giant seahorses alongside swimming dolphins and manta rays
 Sugar skull mariachi in an embroidered sombrero points two guns at the viewer beside stylized title text
 Young boy builds toy blocks as a glowing magical teddy bear floats above a block castle in a cozy nighttime bedroom
More like this
See all →
Made on BudgetPixel
The models and tools behind posts like this one.